DATA ENGINEERING
Data preparation
Quality checks and reproducible transformation of the source dataset.
PythonpandasNumPyExcel / CSV
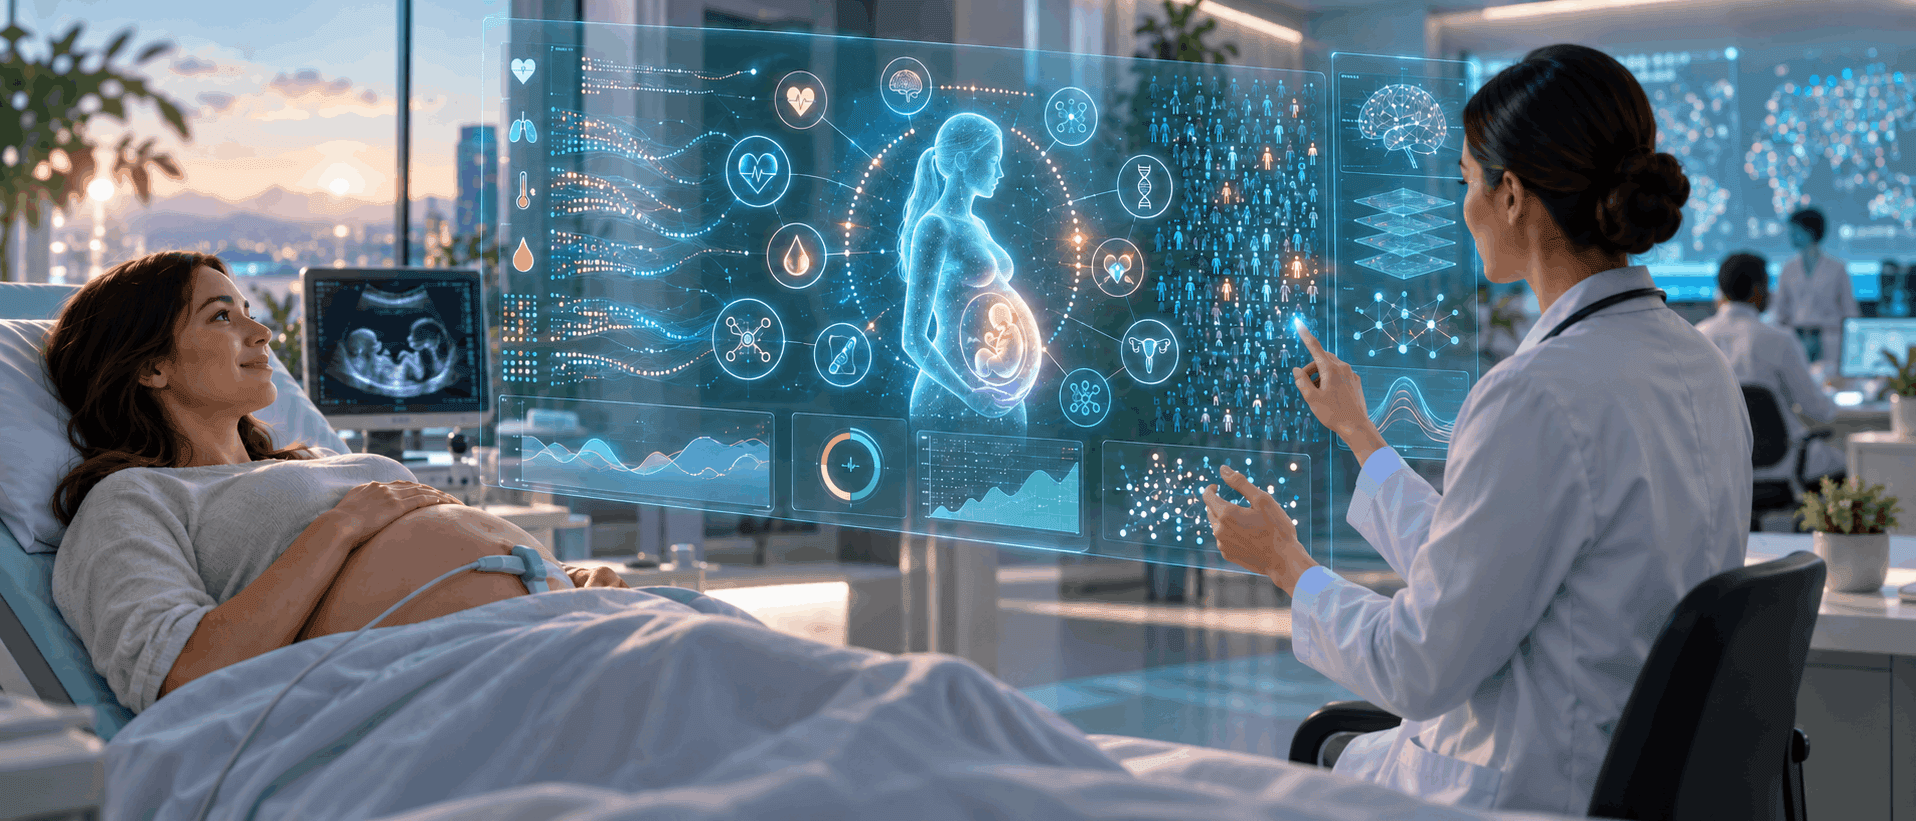
Machine-learning analysis of 15,000+ clinical observations and about 85 source parameters to identify patterns associated with gestational diabetes risk.
Gestational diabetes risk depends on many factors. Together with the obstetrics and gynaecology department of St. Petersburg Pediatric University, I set up a research workflow to examine clinical observations and test candidate predictors.
The prepared dataset and the origin of each feature must remain traceable.
The value is not a single model score. It is a traceable path from the source table through quality checks and feature preparation to validation and clinical interpretation.
Check the clinical table structure, field types and availability of the target variable.
Data structureFind missing values, duplicates, outliers and inconsistent category values.
Quality issuesDefine reproducible cleaning and transformation rules while preserving feature provenance.
Prepared dataExplore distributions and relationships, prepare numerical and categorical features, and check for leakage.
Feature matrixCompare classification approaches on held-out data and examine missed meaningful cases separately.
Validation resultIdentify patterns and predictors that can be discussed substantively with medical specialists.
Auditable predictorsQuality checks and reproducible transformation of the source dataset.
Distributions, anomalies and relationships between clinical parameters.
Feature selection, classification and evaluation on held-out data.
The analysis surfaced patterns and predictors associated with gestational diabetes risk. The prepared feature matrix and the reasoning behind the classification can be reviewed with medical specialists; the work remains in a research setting and does not replace clinical judgement.
Let’s review the source data, constraints and risks, then define a useful first stage that can actually be measured.